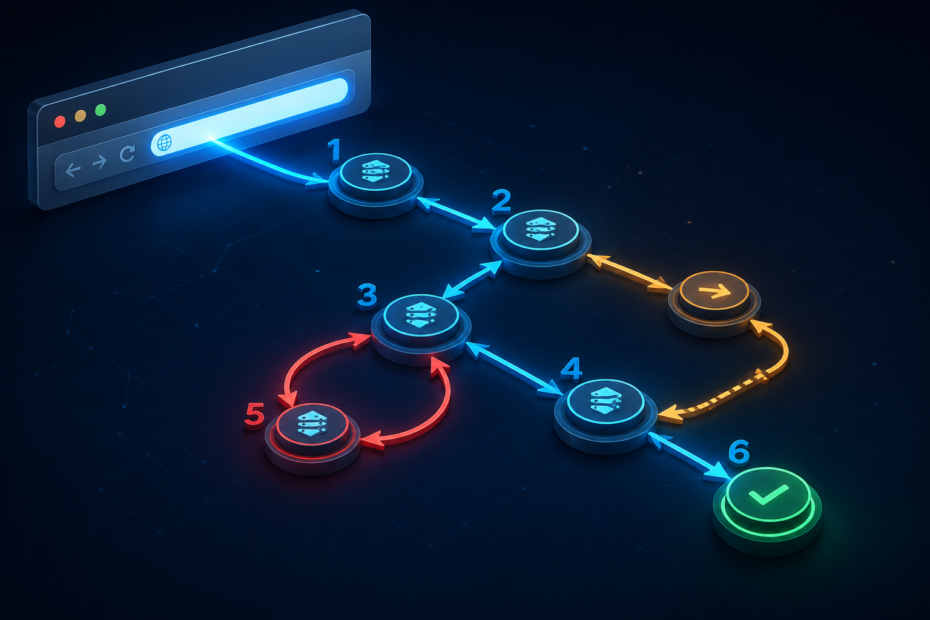
A redirect problem rarely starts with the message users see. One person gets ERR_TOO_MANY_REDIRECTS. Another sees the old URL in Google and lands on an unexpected page. A migration appears complete, but the browser still makes three or four unnecessary hops before it reaches the final destination. In each case, the real question is not “Do I have a redirect?” It is “Which hop is wrong, and which layer created it?”
Before changing a plugin, CDN rule, Nginx block, or application route, run the URL through URL Redirect Checker so you can see every hop, the status code used at each step, and the final destination. That gives you a trace you can reason about instead of guessing whether the problem lives at the edge, the web server, the CMS, or the app.
This guide focuses on the operational problem real users keep reporting: a redirect path that looks simple on paper but becomes a chain, a loop, or a wrong landing page in production. The goal is to read the path correctly, identify the owning layer, remove unnecessary hops, and retest after the fix.
What a healthy redirect path looks like
A healthy redirect is boring. The old URL receives one deliberate redirect and sends the user directly to the page that should replace it. If an old article moved to a new slug, a single permanent hop to the new canonical address is fine. If a short-lived promotion needs to point traffic somewhere else for a week, a temporary redirect may also be fine.
Problems start when the path becomes longer than intended or never reaches a stable final page. That usually happens after redesigns, HTTPS changes, non-www to www decisions, plugin swaps, CDN rule additions, or application-level rewrites layered on top of older server rules.
| Pattern | What it means | Usually acceptable? | Main risk |
|---|---|---|---|
| Old URL → 301 → final URL → 200 | One permanent move to the intended destination | Yes | Low, if owned links are updated over time |
| Old URL → 301 → intermediate URL → 301 → final URL → 200 | A redirect chain with extra hops | No, clean it up | Slower requests, harder debugging, crawl waste |
| HTTP URL → 301 → HTTPS URL → 200 | Protocol normalization | Yes, if it is the only hop | Can turn into a loop when other layers disagree |
| URL A → 302 → URL B → 302 → URL A | A loop | No | Browser failure and inaccessible page |
| URL → 302 → new page for months | A long-term move marked temporary | Usually no | Mixed signals about the intended canonical URL |
Google's redirect guidance makes the practical point here: when a move is permanent, use a permanent server-side redirect, and keep chains low. Migration guidance also says to update your own links and references so they point directly to the final destination instead of forcing every request through old redirects forever.
How to read a redirect trace step by step
A redirect report is most useful when you read it like a sequence of decisions. Start at hop one and ask what each layer told the client to do next.
Requested URL
This is the exact address the client tried first. Confirm whether it is the URL you expected to test. Many production problems begin with a surprise input: a link shortener, a tracking parameter version, an old HTTP bookmark, or a non-www hostname that no one realized was still circulating.
Status code
The status code tells you whether the server is saying “go somewhere else,” and whether that move is intended as permanent or temporary. Do not reduce this to “301 good, 302 bad.” The right code depends on the real intent of the move and, in some cases, the HTTP method being preserved.
| Code | Normal meaning | Operational note |
|---|---|---|
| 301 | Permanent redirect | Good fit for a durable move when the new URL should replace the old one |
| 302 | Temporary redirect | Useful for short-term routing; easy to leave behind by accident |
| 303 | See other | Often used after form submissions when the client should fetch a different URL |
| 307 | Temporary redirect with method preservation | Safer when request method and body must stay intact |
| 308 | Permanent redirect with method preservation | Permanent move that keeps the method and body intact |
| 200 | Final success response | The page finally loaded; inspect whether it is the intended page |
MDN documents an important nuance for application and API traffic: 307 and 308 preserve the request method and body, while older behavior around 301 and 302 may not. That is why changing redirect codes casually can break non-GET flows even when the page seems fine in a browser.
Location target
Each redirect should tell you exactly where the client is being sent next. Read every target literally. This is where you spot a surprise domain, a doubled path, a trailing-slash mismatch, an old staging hostname, or a jump back to a version of the URL that should already be retired.
Final destination
The last URL in the trace should be the page you actually wanted. A request can end with a clean 200 and still be wrong if it lands on the homepage, the wrong regional section, an outdated slug, or a generic catch-all page instead of the intended replacement.
Timing and total hops
One extra hop may not feel dramatic in isolation, but chains add latency and complexity. More importantly, a long chain usually tells you that ownership is unclear. Someone added a new rule without removing the old one, or a migration landed on top of an earlier migration instead of mapping the original old URL straight to the current final target.
The four redirect failures that matter most
1. Migration chains that never got flattened
This is common after multiple redesigns. An old URL redirects to a 2022 slug, which redirects to a 2024 category path, which redirects to the current URL. The page still loads, so the chain survives for months. Google's site-move documentation explicitly advises keeping chains low and sending users directly to the final destination whenever possible.
The fix is not “add one more rule.” The fix is to rewrite the first old URL so it points directly to the final current URL, then update any owned references that still hit the intermediate locations.
2. Protocol or hostname normalization loops
These usually involve overlapping ownership between layers. A CDN may force HTTPS while the origin believes it should redirect back to HTTP under a certain condition. A server block may redirect non-www to www while the application or reverse proxy redirects back in the opposite direction. Cloudflare documents this family of problems clearly in its too-many-redirects troubleshooting: conflicting encryption or redirect settings can create a loop even when each rule looks individually reasonable.
When you see a loop, stop thinking in terms of one “bad redirect” and start thinking in terms of two layers disagreeing about the canonical protocol or hostname.
3. Temporary codes left in place for permanent moves
Teams often use a temporary redirect during a launch window and never return to replace it. The page works, but the long-term canonical signal stays ambiguous. Google's redirect documentation distinguishes permanent and temporary redirects for exactly this reason. If the old URL is not coming back, the redirect should reflect that permanent intent.
4. Internal links, canonicals, or sitemaps still point to old URLs
A redirect chain is often only the visible symptom. The deeper problem is that your own site still references the old address in navigation, body links, XML sitemaps, hreflang, ads, feeds, email templates, or canonical tags. If your site keeps generating old URLs, the redirect will remain hot forever. The clean fix is to update owned references so users and crawlers request the final URL first.
How to identify which layer owns the bad hop
The fastest way to fix redirects is to identify ownership early. Each hop comes from somewhere specific.
CDN or edge layer
Look here when the redirect appears before the request reaches the origin, or when protocol and hostname normalization are happening outside the application. Signs include edge-managed HTTPS behavior, page rules, redirect rules, workers, or proxy-specific headers. If the loop only exists through the CDN path, the edge layer is a prime suspect.
Web server layer
Nginx and Apache commonly own domain canonicalization, trailing slashes, index-file cleanup, and broad rewrite rules. If the redirect is consistent across static files and app pages, and especially if it affects whole hostnames, server configuration is often involved.
CMS or plugin layer
WordPress redirect plugins, SEO plugins, and permalink helpers can add application-level redirects after the request already reached the app. If the server configuration looks clean but a specific post type, archive, or login flow loops or hops, the CMS layer deserves attention.
Application router
Modern frameworks can redirect in middleware, route guards, locale negotiation, auth checks, and error handling. These are easy to miss because they may only affect certain paths, languages, signed-in states, or devices. A redirect that appears only on a subset of app routes often belongs here.
When in doubt, compare the redirect path for a simple static asset, the homepage, and the problematic URL. Differences between them help narrow the owning layer quickly.
How to repair a redirect chain safely
- Write down the old URL and the exact final URL that should replace it.
- Flatten the path so the first request goes straight to the final destination.
- Remove or narrow obsolete intermediate rules that were only needed during earlier migrations.
- Update internal links, canonicals, hreflang, sitemaps, ads, and templates so they reference the final URL directly.
- Retest the old URL, the final URL, and one or two representative variants such as HTTP, HTTPS, www, and non-www.
A useful discipline during migrations is to maintain a one-to-one mapping sheet from each important old URL to its intended new destination. That makes it easier to test staging, validate launch behavior, and prevent “old to previous new to current new” chains from accumulating release after release.
When to use 301, 302, 303, 307, and 308
Use the code that matches the real behavior you want clients and crawlers to understand.
- Use
301when the old URL should permanently give way to the new one. - Use
302when the move is temporary and the original URL is still expected to matter. - Use
303when the client should fetch another resource after a submission or action. - Use
307when the redirect is temporary but the request method must be preserved. - Use
308when the move is permanent and the request method must be preserved.
If your application handles non-GET requests, do not swap redirect types without confirming method behavior. A page-level browser test can hide an API regression.
A practical acceptance matrix after the fix
| Test | Expected result | Why it matters |
|---|---|---|
| Old URL | One deliberate hop to the final URL | Confirms the legacy entry point is clean |
| Final canonical URL | Direct 200 with no redirect | Prevents self-inflicted internal hops |
| HTTP variant | One hop to canonical HTTPS URL | Verifies protocol normalization |
| www/non-www variant | One hop to chosen canonical hostname | Verifies hostname normalization |
| Representative internal links | Direct requests to the final URL | Shows owned references were updated |
| Sitemap and canonical tags | Final URLs only | Prevents search and indexing confusion |
If one of these tests still depends on a redirect, the migration is not truly cleaned up. It may be functional, but it is not final.
What a public redirect checker can and cannot prove
A public checker is excellent for tracing unauthenticated HTTP and meta-refresh behavior on public URLs. It is not a complete simulation of every browser, crawler, bot, cookie state, or geography. The tool used here is clear about its limits: it can test public URLs, show redirect hops, and compare user-agent presets, but it does not execute arbitrary page JavaScript, and a crawler preset changes the User-Agent string rather than proving the request originated from that platform.
That is why a good workflow uses the checker first, then follows up with environment-specific validation if the URL depends on login state, signed parameters, private origins, or region-based behavior. Never paste password-reset links, authenticated URLs, private assets, or tokenized addresses into a public redirect checker.
The shortest path is usually the healthiest one
Most redirect problems are ownership problems in disguise. The wrong page, extra hop, or infinite loop appears because multiple layers are trying to define the canonical path at the same time, or because a new migration was added without retiring the old one. Once you can see the full trace, the job becomes mechanical: identify the bad hop, decide which layer owns it, flatten the path, and retest the important variants.
If a redirect exists for a good reason, keep it simple and direct. If it exists only because the stack inherited history from earlier launches, clean it up now. One clear hop is easier for users, easier for debugging, and easier to maintain than a redirect path that only makes sense to the person who built it two redesigns ago.
